The highest leverage move in any retrieval-augmented pipeline is splitting prompt work across three surfaces: the retrieval prompt, the system prompt, and the synthesis prompt, each doing one job instead of all three fighting for the same tokens. Layer in four production patterns, explicit citation, groundedness framing, chunk formatting, and negative handling, and most silent hallucinations disappear. The rest of this piece hands you the exact skeletons, stress tests, and rollout checklist to make that real.
TL;DR:
- Separating retrieval, system, and synthesis prompts ensures clearer responsibilities and prevents instructions from getting buried, improving answer quality.
- Using retrieval patterns like HyDE, query expansion, contextual continuity, and multi-query decomposition significantly enhances the relevance and quality of retrieved chunks.
- Ground-only instructions, extract-then-answer scaffolds, and chain-of-thought grounding in synthesis prompts reduce hallucinations and improve answer reliability.
- Implementing explicit citation, groundedness framing, chunk formatting, and negative handling as reusable patterns increases system trustworthiness and auditability before deployment.
- Testing prompts with uncoverable, partial, and conflicting query scenarios ensures robustness and prevents silent failures in real-world RAG applications.
Table of Contents
- Where Do RAG Prompt Patterns Belong: Retrieval, System, or Synthesis?
- Which Retrieval Prompt Patterns Improve Chunk Quality?
- What Synthesis Prompt Patterns Reduce Hallucination?
- What Are the Four Reusable Production Patterns Every RAG Prompt Needs?
- When Should Agentic RAG Behavior Live in the Prompt Instead of the Architecture?
- How Do You Test RAG Prompts Before Shipping Them?
- What Copy-Paste RAG Prompt Templates Work for Common Use Cases?
- What Belongs on a RAG Prompt Rollout Checklist?
- A Working Engineer's Take on RAG Prompt Discipline
- Manage Your RAG Prompt Library Without the Copy-Paste Chaos
- Sources
- FAQ
Where Do RAG Prompt Patterns Belong: Retrieval, System, or Synthesis?
Most teams write one giant prompt and wonder why the model ignores half of it. Separating responsibilities across the three surfaces fixes that, and it's the foundation of every reusable RAG prompt pattern that follows.
The retrieval prompt rewrites or expands the user's query before it hits your vector store or search index. It has one job: get better chunks back. The system prompt is persistent, it defines the model's role, its scope boundaries, and its refusal behavior for the entire session or request. The synthesis prompt is dynamic. It's assembled per request from the retrieved chunks plus formatting and citation instructions.
Here's the practical split that keeps token budgets sane and instructions unambiguous:
- Retrieval prompt: query rewriting, HyDE generation, multi query decomposition
- System prompt: persona, domain scope, refusal protocol, tone rules that never change
- Synthesis prompt: citation format, groundedness constraints, chunk-specific answer instructions
Mixing these up is the single most common mistake we see. Put a citation rule in the system prompt and it gets buried under fifteen other persistent instructions by the time the model reaches the actual answer. Put refusal logic in the synthesis prompt and you have to rewrite it every time your retrieval pipeline changes. According to Microsoft Azure's architecture guidance, conversational RAG and graph-backed RAG require different prompt structures entirely, which is exactly why the retrieval layer needs its own dedicated instructions rather than inheriting whatever the system prompt says.
Which Retrieval Prompt Patterns Improve Chunk Quality?
Bad retrieval guarantees bad answers, no matter how good your synthesis prompt is. Four patterns consistently improve what comes back from the vector store.
- HyDE (Hypothetical Document Embeddings). Ask the model to draft a plausible answer to the query first, then embed that hypothetical answer instead of the raw query. Answer-shaped text matches document-shaped text better than a short question does, which is precisely why HyDE outperforms direct query similarity in cases where the phrasing gap between question and source is wide.
- Query expansion. Inject domain synonyms and technical variants directly into the retrieval prompt. Something like: "Rewrite this query to include alternate technical terms, acronyms, and common misspellings a user might use for the same concept." MachineLearningMastery's breakdown of RAG prompt patterns treats query expansion and HyDE as the two core retrieval-side levers worth automating.
- Contextual continuity. Only fold prior turns into the retrieval query when they resolve an ambiguous pronoun or missing referent. Passing the full chat history into every retrieval call bloats the query and drags in irrelevant context. Products built on conversational RAG, like Otto's chief-of-staff assistant, depend on this kind of selective context carry-over to keep multi-turn sessions coherent without polluting every retrieval call.
- Multi-query decomposition. For multi-hop questions ("Compare the 2023 and 2025 pricing changes"), split the query into sub-questions, retrieve for each independently, then merge chunk sets before synthesis.
Pro Tip: Run HyDE and a raw-query retrieval side by side during development and log which one returns higher-scoring chunks for your actual document set. The winner varies by domain, and guessing wastes a week.
For teams building agentic retrieval loops, a dedicated query rewriter prompt that handles expansion and decomposition as a standalone step tends to outperform folding that logic into a single monolithic retrieval call.
What Synthesis Prompt Patterns Reduce Hallucination?
Retrieval gets you the right chunks. Synthesis prompts decide whether the model actually uses them or just wanders off and improvises anyway.
- Ground-only instructions. The phrase that works in production is more specific than "use only the context." Try: "Answer using only information present in the numbered context blocks below. If the answer is not present, say so explicitly and do not guess." Vague versions of this instruction get ignored more often than specific ones.
- Extract-then-answer scaffolds. Force a two-step structure: first, have the model quote the exact sentence or phrase supporting each claim; second, generate the answer from those quotes. This catches hallucination before it reaches the final response, because the extraction step exposes gaps early.
- Chain-of-thought grounding. Require the model to state which chunk supports each claim before writing the conclusion. A working template: "For each claim you make, first cite the source chunk ID, then state the claim." This forces evidence-first reasoning instead of conclusion-first justification.
- Contrastive summaries. When chunks disagree (updated pricing vs. an older doc, conflicting policy versions), instruct the model to surface the disagreement instead of picking one silently: "If sources conflict, state both positions and identify which source is more recent or authoritative."
Pro Tip: Test your ground-only instruction against a question you know isn't covered by any retrieved chunk. If the model answers anyway instead of flagging the gap, your grounding language is too weak, no matter how confident the output sounds.
A production-ready template built around this structure lives in PromptChief's project status report RAG prompt, which constrains outputs to retrieved evidence and forces citation before conclusion.
What Are the Four Reusable Production Patterns Every RAG Prompt Needs?
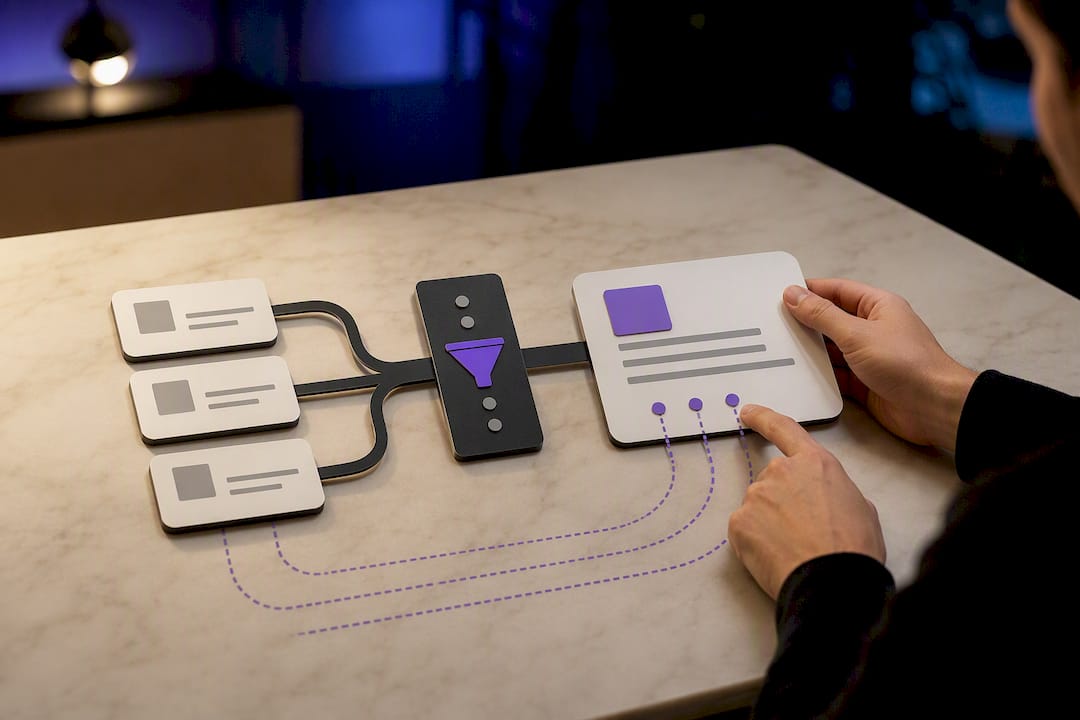
Four patterns, composed together, cover most of the reliability gap between a demo and a production system. SurePrompts' breakdown of retrieval-augmented prompting frames these four as the practical minimum for production reliability, and it holds up.
- Explicit citation. Every claim gets tagged inline: "[Source: doc_id]". Machine-parseable citation formats enable clickable UI tracebacks and automated auditing, which matters far more once you're debugging a wrong answer at 2 AM than it does in a demo.
- Groundedness framing. The instruction that says "answer only from context" plus an explicit fallback behavior when context doesn't cover the question.
- Chunk formatting. Consistent delimiters and IDs around every chunk so the model can reference them precisely. Chunk metadata like title, date, and section label improves citation accuracy even though it costs a handful of extra tokens per chunk.
- Negative handling. A defined "I don't know" protocol triggered when no chunk covers the query, rather than letting the model fill the gap with plausible-sounding invention.
Here's a minimal skeleton for each, meant to paste into a synthesis prompt and adapt:
| Pattern | Minimal fragment | Failure mode it prevents |
|---|---|---|
| Explicit citation | "Tag every claim with [Source: chunk_id]." | Untraceable claims, no audit trail |
| Groundedness | "Use only the context below. If insufficient, say so." | Confident hallucination on uncovered topics |
| Chunk formatting | "[Chunk 1, id: doc_42, section: pricing]... content..." | Ambiguous or merged source attribution |
| Negative handling | "If no chunk answers the question, respond: 'I don't have enough information.'" | Silent guessing dressed up as an answer |
PromptChief's production-ready system prompt bakes several of these fragments together as a starting point rather than four disconnected rules.
When Should Agentic RAG Behavior Live in the Prompt Instead of the Architecture?
Some behaviors belong in the prompt. Others need an actual architectural change, and confusing the two wastes engineering time on prompt tweaks that were never going to fix a retrieval problem.
Azure's architecture guidance argues that advanced agentic RAG systems should move from static instructions to behavioral definitions, meaning the prompt should specify conditions for action, not just tone and format.
- Re-query thresholds. Define the signal explicitly: "If retrieval confidence score is below 0.6, or fewer than two chunks overlap with the query terms, issue a reformulated query before answering."
- Tool invocation. Give the model a narrow, named fallback: "If the question requires current pricing and no chunk is dated within 90 days, call the pricing_lookup tool rather than answering from stale context."
- Self-verification. Add a final check step: "Before returning your answer, re-read each claim against its cited chunk. If a claim isn't supported, remove it or flag it as unverified."
Where the boundary sits matters: if re-querying never improves results because your retrieval index itself is thin, that's an architecture fix, not a prompt fix. The query rewriter pattern handles the prompt side of re-query logic well, but it can't compensate for missing documents.
How Do You Test RAG Prompts Before Shipping Them?
Three test cases catch most silent failures before they reach production, and running them automatically on every prompt change is worth the CI overhead.
- Uncoverable Query test. Ask a question with zero relevant chunks in the corpus. Pass criteria: the model states it lacks sufficient information, no invented answer.
- Partial Context test. Provide chunks that partially answer the question. Pass criteria: the model answers the covered portion and explicitly flags what's missing.
- Conflict test. Feed two chunks with contradictory information. Pass criteria: the model surfaces both positions rather than silently picking one.
MachineLearningMastery's guidance on RAG implementation patterns backs this test-first approach as the difference between a prompt that looks fine in a demo and one that survives real traffic.
Track these metrics across runs: refusal rate on uncoverable queries, citation density per response, and a count of unsupported-claim flags caught by your extraction step. Log the retrieved chunk IDs, the final prompt sent, and the raw model output for every test run, that's your minimal audit trail when something breaks downstream.
A working benchmark: a prompt that passes all three canonical tests at a consistent rate across a few hundred sampled queries is a reasonable bar before staging deployment; one that fails the Conflict test regularly usually means your groundedness framing is too weak, not that the model is broken.
What Copy-Paste RAG Prompt Templates Work for Common Use Cases?
Three flows cover most real-world RAG deployments: documentation QA, support ticket resolution, and multi-source synthesis. Each needs slightly different chunk ordering and citation density.
- Documentation QA: high citation density, strict ground-only framing, chunks ordered by relevance score descending.
- Support flows: groundedness plus a tone layer in the system prompt, since support answers need both accuracy and a human register.
- Multi-source synthesis: contrastive framing is mandatory here, since sources are more likely to disagree across time or department.
A ground-only template with citation rules, adapted for documentation QA:
Chunk delimiter conventions matter more than most teams expect. A consistent format like [Chunk N | id: doc_id | section: label | date: YYYY-MM-DD] followed by the chunk text gives the model unambiguous handles to cite, and it keeps your extraction step from misattributing a claim to the wrong source. The agentset-ai/rag-prompts repository has copyable versions of strict grounding, extractive, chain-of-thought, and multi-source comparison prompts you can adapt directly rather than writing from scratch.
What Belongs on a RAG Prompt Rollout Checklist?
Shipping a new prompt pattern without a checklist is how teams end up debugging a hallucination in production instead of catching it in staging.
- Confirm every chunk carries metadata: source ID, title, date, section label.
- Verify the citation format is machine-parseable and matches what your UI expects to render.
- Run all three stress tests (uncoverable, partial context, conflict) and record pass rates.
- Set a token budget per chunk and per total context window, and confirm you're under it with headroom.
- Assign an owner for prompt versioning so changes are tracked, not overwritten silently.
| Checklist item | Acceptance bar |
|---|---|
| Chunk metadata present | Most chunks tagged with ID, date, section |
| Citation format parseable | UI renders clickable source links |
| Stress test pass rate | Consistent pass on all three canonical tests |
| Token budget | Context window has documented headroom |
| Version ownership | Named owner, changelog per prompt revision |
Maintenance cadence matters as much as the initial rollout. Revisit prompts whenever the underlying document corpus changes shape, not just on a calendar schedule.
A Working Engineer's Take on RAG Prompt Discipline
The mistake I see most often isn't a missing pattern, it's stuffing every instruction into one prompt and hoping the model prioritizes correctly. It won't. The second mistake is chasing coverage over precision: a model that answers everything confidently is worse than one with a well-designed fallback. Version your prompts like code, with small testable diffs, because a "minor" wording change to a citation instruction can shift refusal rates more than a full retrieval pipeline rewrite.
— John
Manage Your RAG Prompt Library Without the Copy-Paste Chaos
Every pattern in this article, retrieval rewrites, system prompts, citation skeletons, negative-handling fallbacks, needs a home somewhere other than a scattered folder of text files. That's the gap Prompt Management closes: cloud-synced template libraries that keep your production RAG prompts versioned and consistent across every environment, instead of copy-pasted between a teammate's Slack message and your codebase.
Store your system prompt, your groundedness fragments, and your citation format skeletons as reusable, searchable templates, then inject them straight into ChatGPT, Claude, or whatever model you're testing against, without retyping a single fragment. Run quick side-by-side variants of a synthesis prompt to see which citation phrasing actually holds up against your conflict test, and share the winning version across your team's workspace so nobody ships an outdated grounding instruction. Start organizing your RAG prompt library with a Prompt Management workspace and stop losing track of which prompt version is actually live.
FAQ
What Are RAG Design Patterns?
RAG design patterns are reusable prompt and architecture structures, like query expansion, groundedness framing, explicit citation, and negative handling, that make retrieval-augmented systems produce accurate, traceable answers instead of confident guesses.
What Is a RAG Prompt?
A RAG prompt is any instruction given to a model within a retrieval-augmented pipeline, split across a retrieval prompt that improves search results, a system prompt that sets persistent rules, and a synthesis prompt that governs how the final answer is generated from retrieved chunks.
Is ChatGPT a RAG Model?
ChatGPT is a language model, not a RAG system by itself, but it becomes part of a RAG pipeline when connected to an external retrieval step, such as a vector search or document lookup, that feeds it context before it answers.
What Are Some Good RAG Projects to Practice On?
Documentation question answering, internal support ticket resolution, and multi-source synthesis across conflicting documents are strong starting projects because each forces you to practice a different pattern: strict grounding, citation formatting, and contrastive handling, respectively.